Python sets and dictionaries can have quadratic-time performance
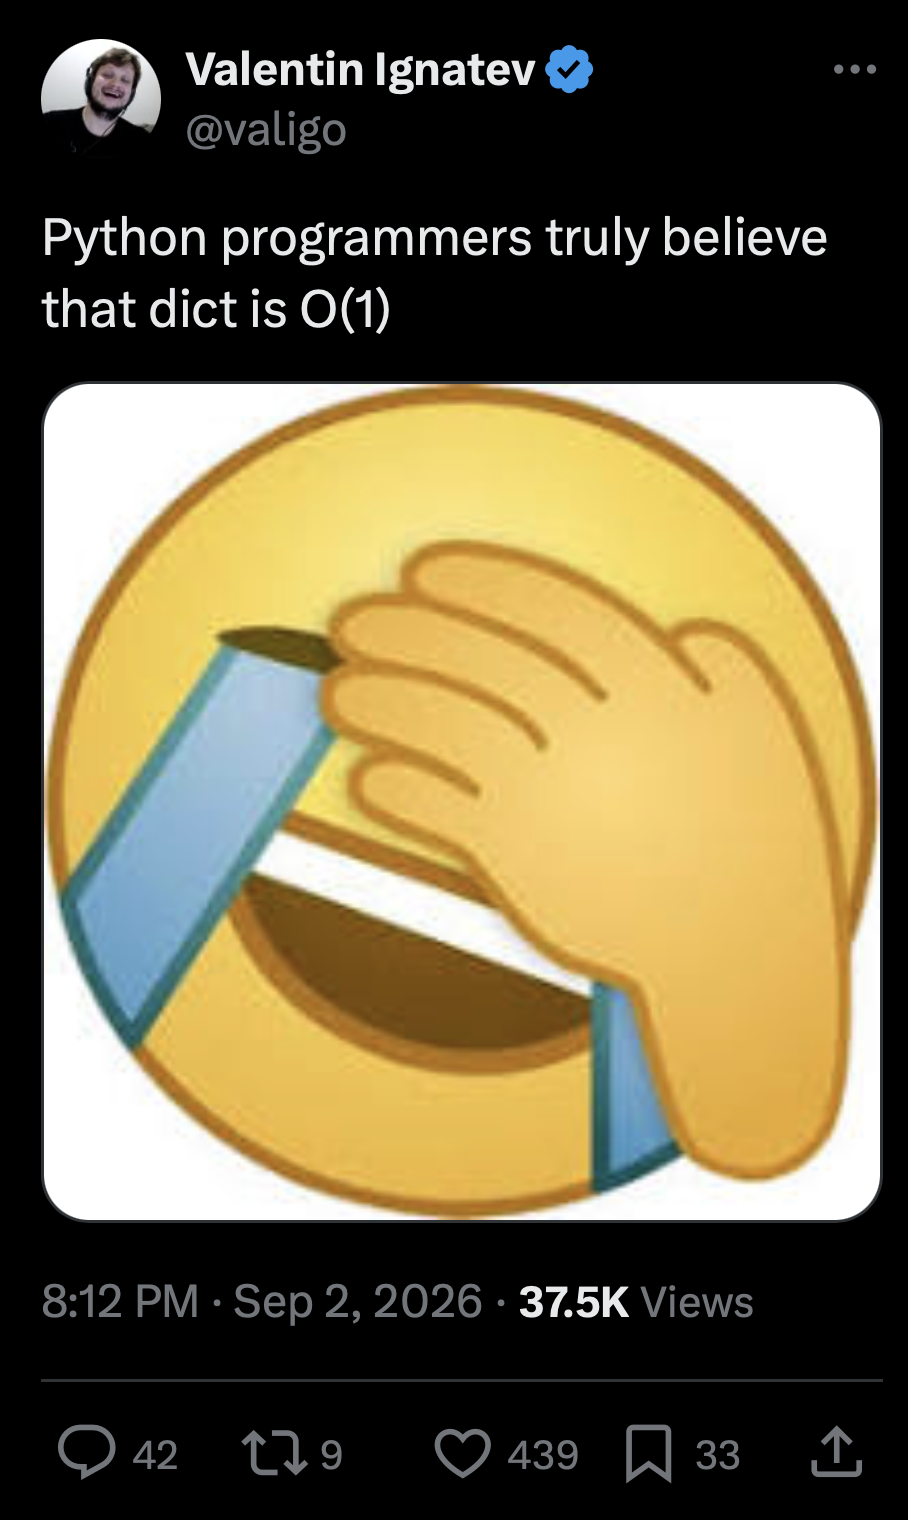
In Python, the dict data structure is the conventional key-value structure. E.g., you might store a list of names as keys and have their phone numbers as values. Valentin Ignatev wrote this amusing post on X:
It is indeed widely believed that, in the strict sense, the dict data structure and its companion, the set data structure, are O(1), meaning that as you increase the size of the data structure, the time to insert or query a key remains constant.
Let us examine the claim.
A hash function is a function from objects (like strings, integers, etc.) to integer values. We typically expect hash functions to be random-like, although they should always map the same object to the same integer within the current program execution. From hash functions, we construct hash tables:
- Create an array of buckets.
- Given an object, apply the hash function to map it to a bucket.
- Store the object in the bucket. When the bucket is already occupied, use some other trick (such as using a nearby bucket).
If everything goes well, access and insertion in a hash table take nearly constant time, meaning that the time they take is independent of the size of the hash table.
This can be almost true in many instances. However, it is not formally true. There are many reasons why it is false. For example, if your data structure grows, it might be necessary to reallocate, which will typically take time proportional to the size of the data structure. But we also have the issue of collisions. A collision is what happens when two objects have the same hash value. When we use hash tables, we assume that collisions are uncommon. But it is not difficult to create many of them by picking our objects carefully.
In Python, set and dict are hash tables. I can ‘easily’ make my version of Python crumble:
M = (1 << 61) - 1
values = [i * M for i in range(1, n + 1)]
s = set(values) # insertions
count = sum(v in s for v in values) # checks
If the insertions and the checks are constant-time operations, then the whole construction and the entire check should take linear time. I ran this on an Apple M4 Max with Python 3.14, reporting the median of three runs.
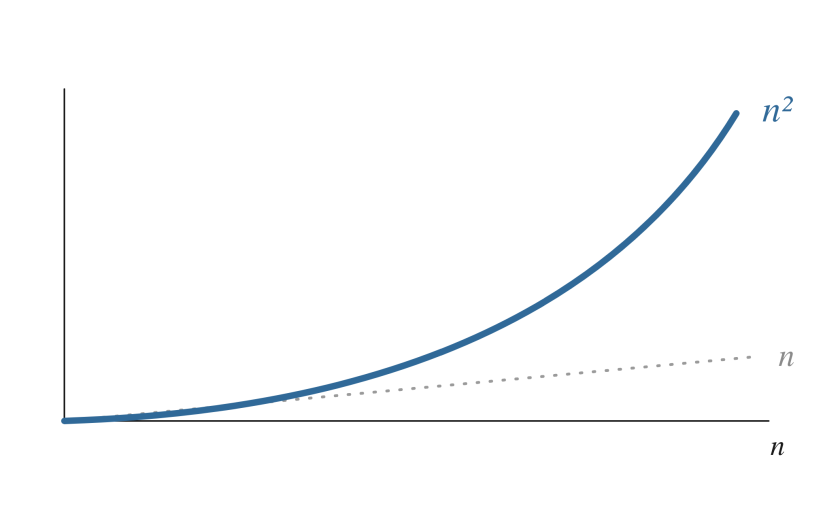
The time roughly quadruples each time n doubles. That is quadratic time, not linear time. The membership checks behave the same way: 1066 ms at n = 16000. At a hundred thousand elements, building the set takes 45 seconds.
But could we create a hash table that would be truly constant-time? No. As the size of your data structure grows, it requires progressively slower memory. If you have a small hash table, it can reside in the CPU cache and be fast. Once it reaches megabytes in size, the data structure tends to live in RAM, which is much slower. And then, eventually, you have to store it on disk, which is even slower. And so forth.
To put it differently, saying that a hash table is O(1) or constant time is a model. It can be true, maybe even often, but it is not reality. Models are great teaching tools: they present a simplified model that you can quickly learn. But models can also introduce biases in how we think.
For example, even though you have read my paragraph that says that the dict data structure gets slower, you may not believe it. You may also believe that it is typically going to be the fastest approach you can use.
Let us consider another practical case. Suppose that you have a large map from strings to integers, that you build once and then only query. That is a common situation: a dictionary of words to identifiers, a lookup table of country codes, a table of feature names.
The fastconstmap library builds an immutable map from a dict[str, int]. It is suitable when your keys are known in advance.
I build a map from a million random sixteen-character strings to integers, and then look up every key in a shuffled order. With a dict, I write the obvious loop:
total = 0
for k in probes:
total += d[k]
With fastconstmap, I ask for all the keys at once, writing the values into a buffer that I own, so that no Python object is allocated per key:
out = array("Q", bytes(8 * n))
cm.get_many_into(probes, out)
I am being generous to the dict. I reuse the same string objects for the lookups, and a Python string caches its hash value the first time it is computed. So the dict does not pay for hashing at all, while fastconstmap hashes every key every time. Here are the results, in nanoseconds per key.
The dict is not constant time. It goes from 22 ns to 202 ns per key as the map grows, a factor of nine, and it is not because the algorithm changed or because of collisions. It is because a million keys, their string objects, and their integer objects occupy about 116 bytes per key, so the lookups miss in the cache. The fastconstmap version needs 9 bytes per key: it stays in the cache much longer. Pay attention to how the numbers scale: the dict becomes 10 times slower as the size grows.
The lesson is always the same. Some models are useful but none of them is reality. Be mindful of cognitive biases.
The new Go JSON API: twice as fast, or 1.5x slower?
JSON is a standard format for data interchange. It is effectively a tiny subset of JavaScript made of objects and arrays. It looks as follows {"key":1, "text":[1.0,2.0]}.
Many programming languages include a JSON library in their standard libraries: C#, Go, Java (soon), Python, JavaScript, etc. The Go implementation is convenient, but not especially fast.
Go 1.27 makes a new JSON package (encoding/json/v2) available by default in its standard library. The two APIs look almost the same:
import (
json "encoding/json"
jsonv2 "encoding/json/v2"
)
b, err := json.Marshal(v)
b, err = jsonv2.Marshal(v)
err = json.Unmarshal(b, &v)
err = jsonv2.Unmarshal(b, &v)
The two are not directly comparable as they differ with respect to Unicode validation, case sensitivity, etc. So it is not a drop-in replacement.
However, the legacy API (encoding/json) has also been reimplemented on top of the new engine. You can use the legacy API with either the new engine or the old one (GOEXPERIMENT=nojsonv2) through a flag. So we have three possibilities.
- json (legacy) —
encoding/jsonbuilt withGOEXPERIMENT=nojsonv2, the original implementation - json (Go 1.27) —
encoding/jsonas of 1.27, v1 API on the v2 backend - json/v2 —
encoding/json/v2
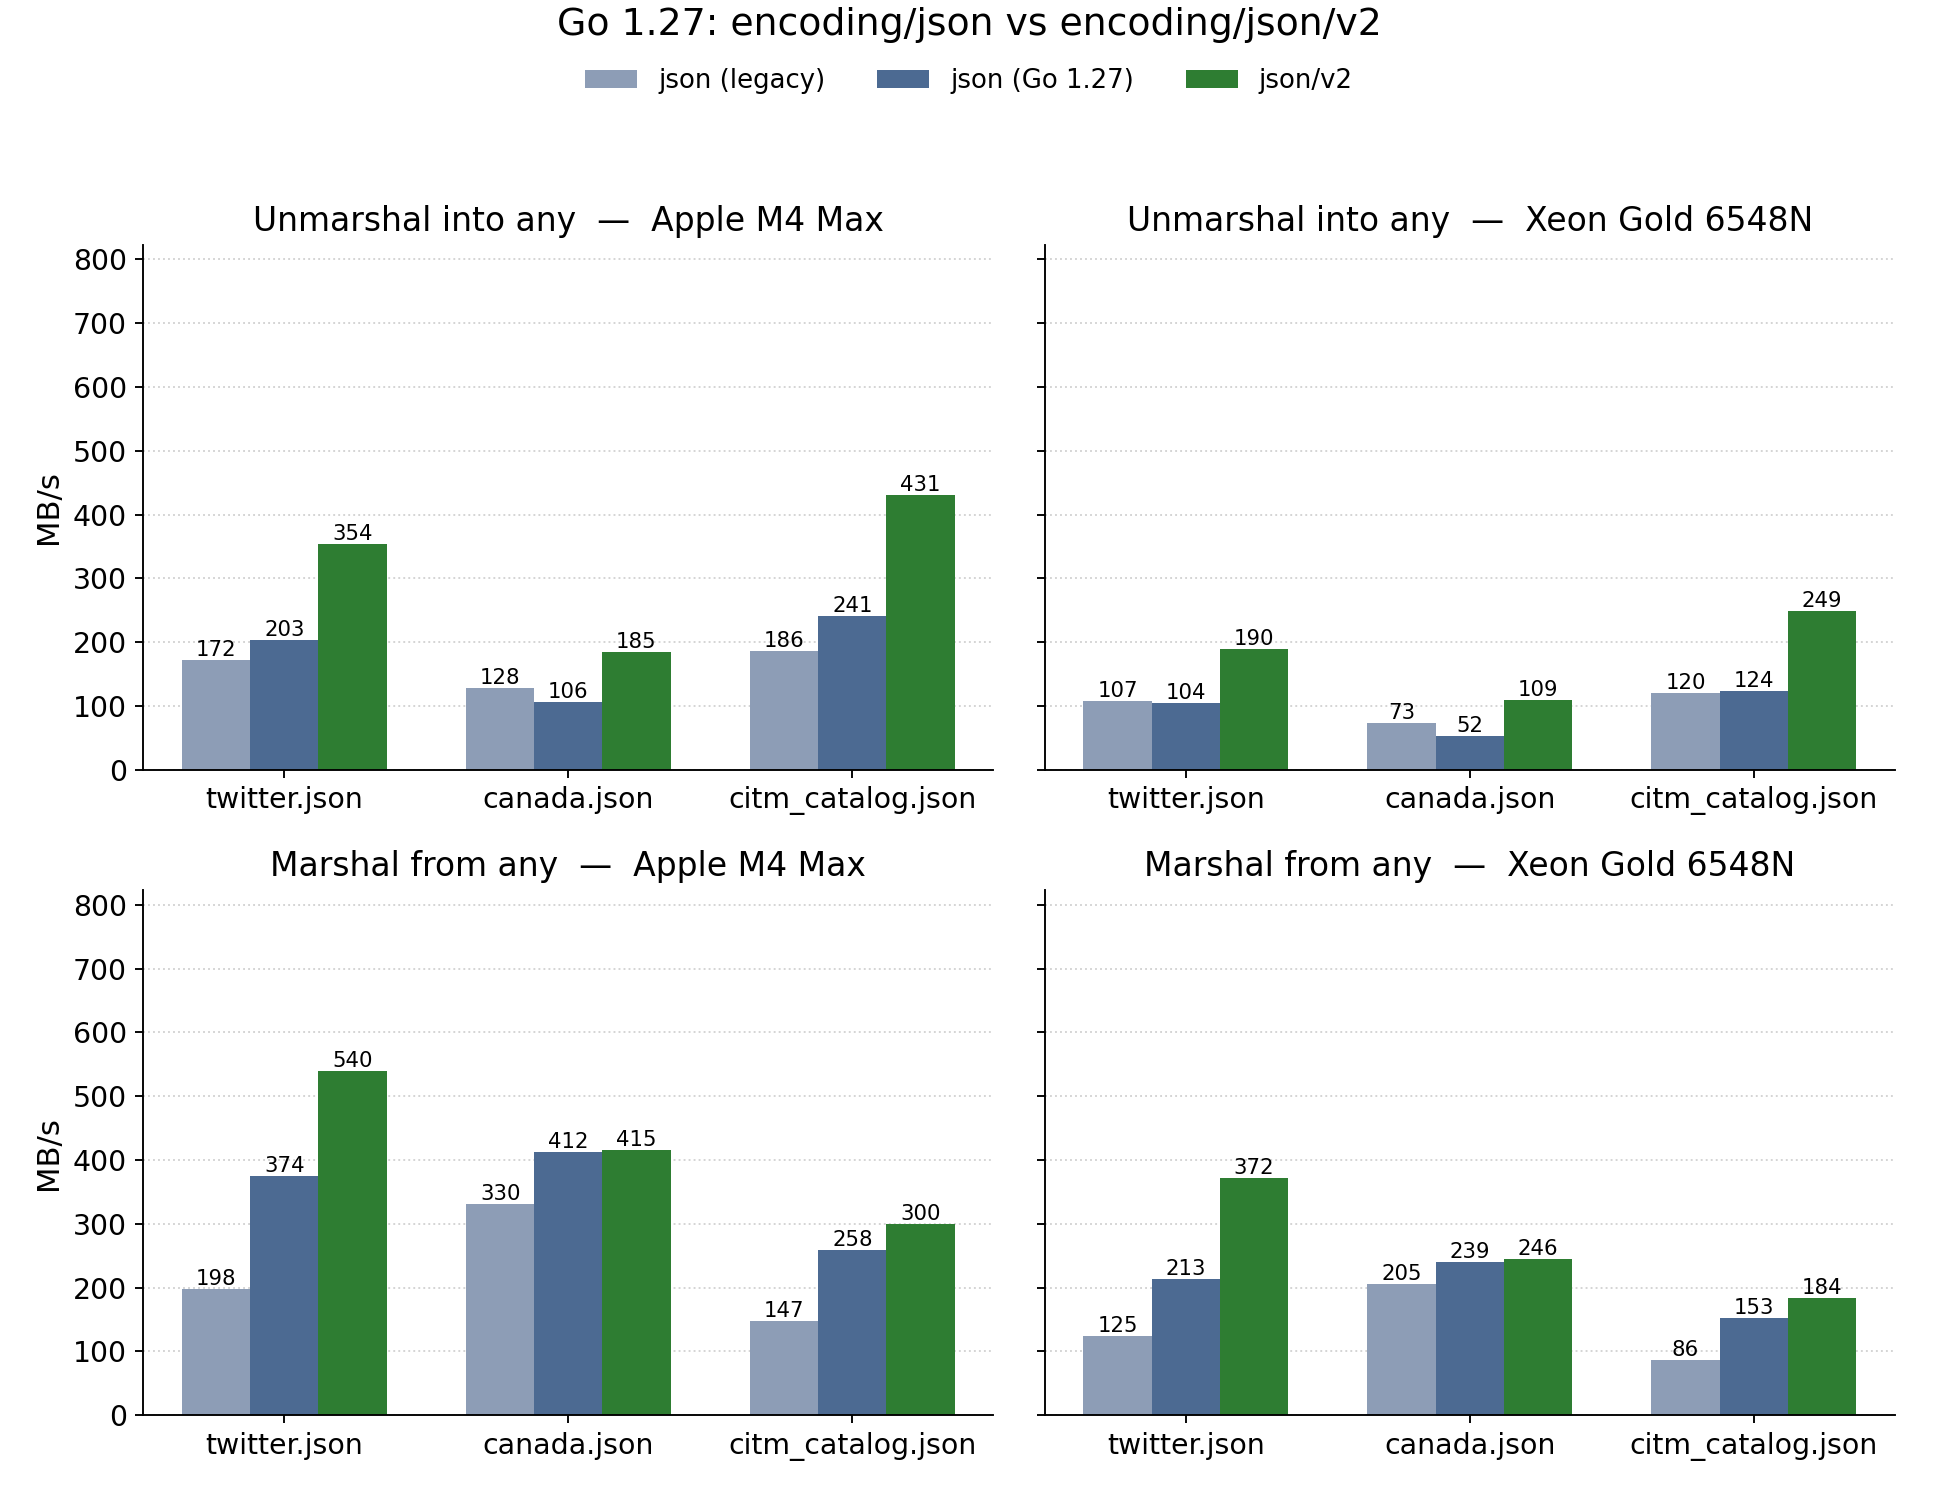
I used the usual simdjson documents: twitter.json (632 kB, nested objects with short string keys), canada.json (2.25 MB, one large array of coordinates), and citm_catalog.json (1.73 MB, nested objects with numeric keys). I parse them into any (interface{}), which is the general-purpose path.
I ran this on an Apple M4 Max and on an Intel Xeon Gold 6548N (Emerald Rapids) using Go 1.27.0, on a single core (GOMAXPROCS=1), reporting the median of eight runs.
When unmarshalling, the legacy API on the new backend is faster than the original on twitter.json (172 MB/s to 203 MB/s) and on citm_catalog.json (186 MB/s to 241 MB/s), but slower on canada.json (128 MB/s down to 106 MB/s). When marshalling, it is up to twice as fast: 198 MB/s to 374 MB/s on twitter.json. So merely upgrading to Go 1.27, without changing a line of code, should make marshalling faster.
Switching to the new API helps more. Compared to the original implementation, encoding/json/v2 unmarshals 1.5x to 2.3x faster and marshals 1.2x to 3x faster. Compared to the Go 1.27 legacy API, unmarshalling gains another 1.8x to 2x, while marshalling gains much less (1.0x to 1.7x): part of the remaining difference is that json/v2 does less work during marshalling.
Thus far, I was unmarshalling into any, meaning that I assumed that I did not know the structure of the document. I also round-trip a slice of 10,000 small structs:
type Record struct {
ID int `json:"id"`
Name string `json:"name"`
Email string `json:"email"`
Active bool `json:"active"`
Score float64 `json:"score"`
Tags []string `json:"tags"`
}
The schema is specified: the JSON must be [{"id":..., "name":...}, {"id":..., "name":...}...]. I still get faster unmarshalling with the new API, but the legacy API with the legacy engine is faster when marshalling.
The original implementation is faster. The Go 1.27 release notes said that marshal performance is broadly at parity with the previous implementation. For my test, it is not the case.
So unmarshalling gets faster across the board with encoding/json/v2, and marshalling gets faster for any, but it is about 1.5x slower for typed structs in my tests.
Java’s String.indexOf can be slow (quadratic)
In Java, you find the location of a substring using indexOf.
String haystack = "The quick brown fox jumps over the lazy dog";
String needle = "fox";
int index = haystack.indexOf(needle);
Naively, you might implement indexOf by a loop inside a loop, like so.
int naiveIndexOf(String haystack, String needle) {
for (int i = 0; i <= haystack.length() - needle.length(); i++) {
int j = 0;
for (; j < needle.length()
&& haystack.charAt(i + j) == needle.charAt(j); j++) {}
if (j == needle.length()) { return i; }
}
return -1;
}
The Java implementation is much more sophisticated, and it is highly accelerated.
However, there are pathological cases where the Java implementation can be slow. What do I mean? Well, you do expect that the search will be more and more expensive as the size of the string grows. Right? So if you search through a 1 kilobyte string and then search through a 10 kilobyte search, you would not be surprised if the latter takes ten times slower.
But what of the substring? If you search for short substrings (fox in my example), the everything is fine. But what if you search longer and longer substrings (fox jumps or fox jumps over)? If it gets more expensive when both the string and the substring get longer, then you have what we call a quadratic complexity. In other words, it is slow.
In Java, if n is the length of your string and m is the length of the substring, then the complexity of indexOf is O(n·m). And if you look at my naive implementation (naiveIndexOf) then you see that in the worst case, it might do up to close to haystack.length() * needle.length() comparisons, that is, it is O(n·m).
The exact implementation of the indexOf function depends on your CPU and Java version. I am using OpenJDK 25 on Apple Silicon (ARM). For my purposes, I will use as a haystack of n copies of a and for the needle, the same thing, but ending with a different letter.
// n > m
String haystack = "a".repeat(n);
String needle = "a".repeat(m - 1) + "b";
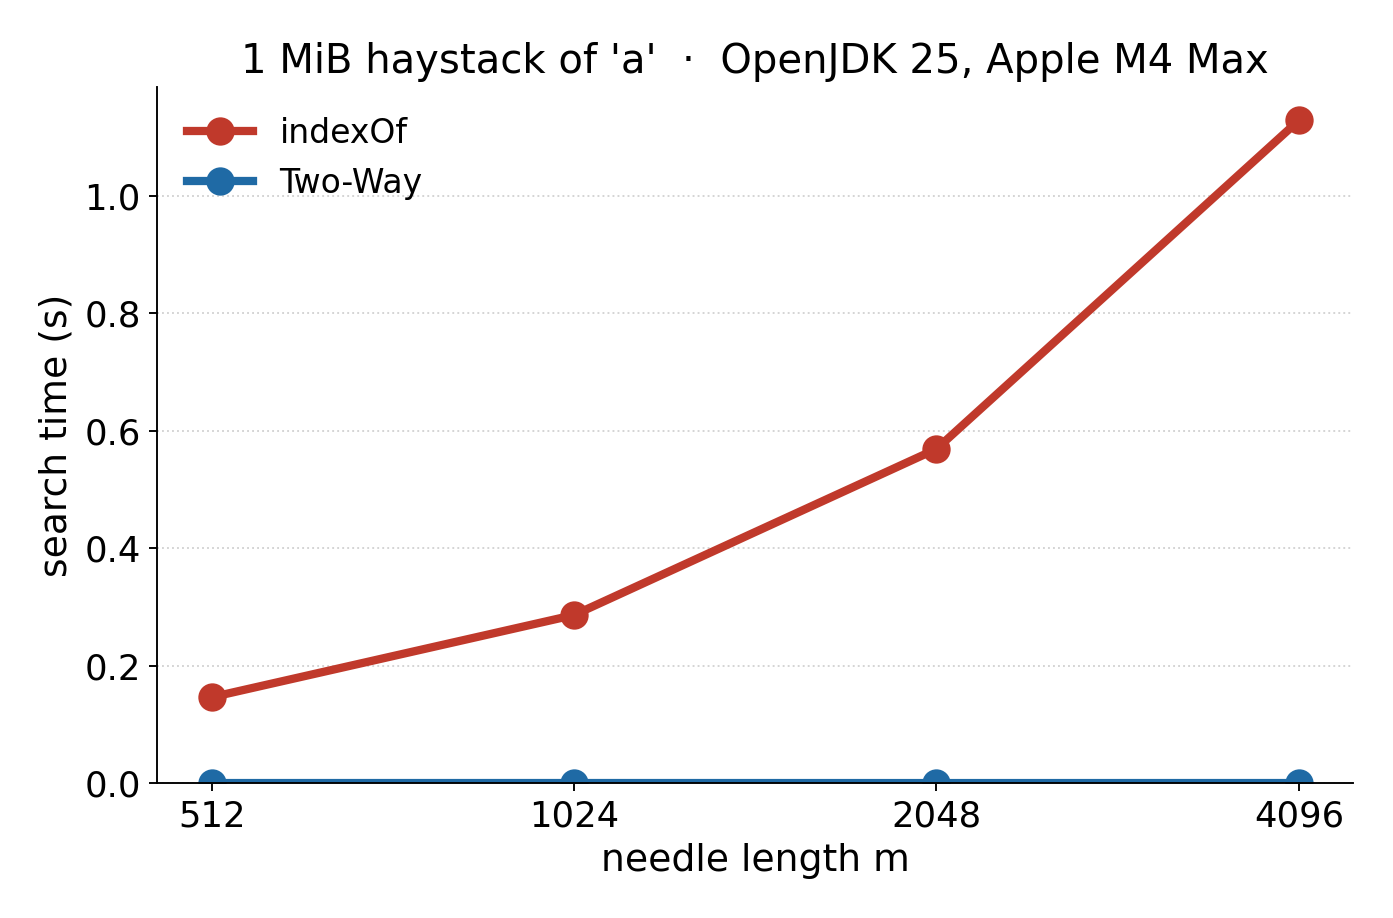
I measured OpenJDK 25 on an Apple M4 Max. The haystack is one megabyte. Numbers are nanoseconds per haystack character.
At m = 4096, a single indexOf over one megabyte takes 1.1 seconds.
Can you do better against such adversarial inputs? The textbook solution is the Two-Way algorithm of Crochemore and Perrin (1991). The implementation is simple and your favourite AI can code it for you in any programming language.
Two-Way stays at about 0.3 ns/character no matter how long the needle is. At m = 4096 it is about 3500 times faster than indexOf on the first-character adversary.
So, should you switch to Two-Way for everything? No. On random text, the indexOf function is much faster than Two-Way.
And Two-Way has to do non-trivial work before the search begins. So it has additional fixed overhead. It would lose most of the time in the real world, sometimes by a wide margin.
Should you worry about this? No. The indexOf function in Java is fine.
If an adversary can control the needle (substring), then make sure to reject long needles. Most of the time, we search for short sequences (say, less than 80 characters). If you are worried about your system crashing, you will put bounds on inputs in any case.
Further reading: Crochemore, M., & Perrin, D. (1991). Two-way string-matching. Journal of the ACM, 38(3), 650–674.
Parsing IP addresses in C# at crazy speeds
We are all familiar with IP addresses such as 192.168.0.1. They are typically written as four numbers in the range 0 to 255 inclusive, separated by dots. In C#, you can parse them with the standard library using IPAddress.TryParse.
Pedantic people are quick to point out that IP addresses can take different forms: they can be IPv6 or IPv4 and there are many weird ways to write an IPv4 address. But for the purpose of performance optimization, we care about the common case. The common case is strings such as 192.168.0.1 or 12.121.244.111.
Our processors are capable of data parallelism, meaning that they have instructions (called SIMD) that can process several bytes at once, at least 16 bytes, sometimes more. A few years ago, I showed that you can parse IPv4 addresses with SIMD. I have been revisiting this idea with AVX-512, the instruction set that recent x64 (AMD/Intel) processors support. I expect that all Intel and AMD processors made in the near future will have great support for AVX-512, and it is already the case for server processors and recent AMD processors.
So I wondered, could we do it in C#? People are sometimes surprised that I care about C#. Isn’t that more Microsoft slop? No. Not at all. C# and .NET are very reasonable, portable systems.
Plus you can write fast code in C#. I have two optimized libraries that I hope the Microsoft .NET team will one day adopt in the standard .NET library: an optimized Utf8Utility.GetPointerToFirstInvalidByte function used internally to validate Unicode strings (in the SimdUnicode library) and a fast base64 decoding library. I love working with .NET C#.
As of .NET 10, we have AVX-512 support, including masked loads. What are masked loads and why do they matter? Suppose that I give you a string that is no longer than 16 bytes, but could be shorter. If you load data in a SIMD register, you normally have to load the full register width (so 8, 16, 32, 64 bytes). So what do you do when it is not possible? You can pad the input string or pull other tricks, but it gets dirty. A nice approach is to have masked loads where you, say, load the full register (say 16 bytes), but you indicate which bytes you want to be loaded from memory with a mask. So if you use 0b10011 as a mask, then only the first, second, and fifth bytes are loaded from memory. This makes it possible to initialize a 16-byte register with a string that has between 0 and 16 bytes, while never reading beyond the string. I have an article entitled Modern vector programming with masked loads and stores if you want to know more.
To make things trickier, C#, like Java and JavaScript, defaults to UTF-16, meaning that each character, even if it is an ASCII character like A or 1, uses two bytes. The ASCII codepoint value occupies the least significant bits of a 16-bit word.
So what we need to do is to selectively load from a 32-byte input, and then drop the unnecessary zero bytes. The gist of it looks as follows in C#.
unsafe bool TryParseAvx512(ReadOnlySpan<char> s, out uint ip) {
int len = s.Length;
fixed (char* cp = s)
{
// next two lines are a trick to load just the first len characters
Vector256<ushort> charMask = Vector256.LessThan(CharLaneIndex, Vector256.Create((ushort)len));
Vector256<ushort> chars = Avx512BW.VL.MaskLoad((ushort*)cp, charMask, Vector256.Create((ushort)'0'));
// check that everything is ASCII otherwise, it is not an IP!
if (Avx512BW.VL.CompareGreaterThan(chars, Vector256.Create((ushort)0x7F)).ExtractMostSignificantBits() != 0)
{
return false;
}
// There we go, we have the address as ASCII
// in a 16-byte register.
Vector128<byte> str = Avx512BW.VL.ConvertToVector128Byte(chars);
// ...
}
}
This looks a bit difficult to read, but that’s fine. Most people never need to worry about such code.
Then we use a somewhat fancy trick where we locate the dots, and use the fact that there are only 81 ways to position the dots. We then move the bytes, do a dot product and validate. It is the same routine as the C++ code. It is not trivial, but I am working on a formal paper to document the tricks used.
The pedantic people will say: wait, there are other ways to write IP addresses !!! Ok fine. We handle them with a fallback, like so.
if (TryParseAvx512(s, out uint ip))
{
address = new IPAddress(ip);
return true;
}
return IPAddress.TryParse(s, out address);
What about the cases where your processor does not support AVX-512? C# makes this dead easy. You can just guard it with one if:
if (Avx512BW.VL.IsSupported) { ... }
To benchmark this, I generated 10,000 random 32-bit addresses and parsed the resulting strings 20 million times, constructing an IPAddress each time. On a relatively recent Intel processor (Intel Xeon Gold 6548N, Emerald Rapids) running .NET 10, I get the following.
So the AVX-512 approach is about three times faster than the standard library. My routine itself does not take fourteen nanoseconds; there is other overhead.
As usual, the C# source is available.
Go 1.27 will make some allocations cheaper
Like most programming languages, Go has both stack allocations, whose lifetime is limited to the current function, and dynamic (or heap) allocations.
The name stack comes from the fact that the memory management is somewhat trivial. There is typically one stack per thread (or goroutine in Go). When a function needs memory, it simply appends data to the stack. When the function returns, the memory is dropped from the end of the stack. So the memory last allocated is deallocated first.
Heap memory is potentially considerably more complex. For one thing, it is meant to be accessible by several threads (or goroutines). An object can be allocated by one function and later reclaimed after an entirely different function, possibly running on a different thread (or goroutine), has dropped the last reference to it. Unlike the stack, there is no prescribed order for allocating and reclaiming heap memory. In Go, the garbage collector does the reclaiming.
Typically, stack allocations have a size known at compile time. Many systems give each thread a fixed-size stack, although Go grows goroutine stacks as needed.
There are many ways in Go to do a heap allocation. A common one is when you allocate a slice, as in this instance where you allocate memory for 100 integers:
x := make([]int, 100)
If the slice x is not entirely local to a function, Go will typically just allocate it on the heap. It will do so similarly when a function returns a pointer. For example, in the following instance, I assign the value 1 to a local integer variable, but I return a pointer to it.
func f() *int {
x := 1
return &x
}
In C/C++, this would be quite bad. You should get a warning such as address of local variable 'x' returned. In Go, the variable x will typically get allocated on the heap.
In many Go programs, we end up doing a lot of heap allocations of small objects. It can become a bottleneck in some cases. Think about when you are maintaining a tree or a linked list where each value (node) is an object that must live on the heap. If the data structure is highly dynamic, you will be constantly allocating these small objects.
Memory allocation on the heap is usually not done at arbitrary sizes. You often cannot get exactly, say, 13 bytes. In Go, small allocations are rounded up to a size class: 8 bytes, 16 bytes, 24 bytes, 32 bytes, and so forth. There is also some overhead to each heap allocation, from rounding and from allocator metadata.
The compiler knows the size of the object, but prior to Go 1.27, Go would call a generic function when doing a heap allocation. This generic function would then look up the size class and take the corresponding path. Starting with 1.27, for small objects (under 80 bytes), Go relies on dedicated functions.
It is easy to benchmark in Go. A basic benchmark might look as follows.
type Node struct {
value int64
next *Node
}
var sink any
func BenchmarkAllocNode16(b *testing.B) {
for b.Loop() {
sink = &Node{}
}
}
On my MacBook, the results are quite telling. Go 1.27 is nearly twice as fast!
This will not help all software, just the components that do many small allocations.
The code is available.
AI programming : are you angry yet?
AI-assisted programming is fast evolving and there is a tension between ‘we no longer need to understand the code’ and ‘what is my purpose as a programmer’. I recorded a short video on this topic with how I think the tension can result in conflicts.
Profile-guided optimization in Go
When a compiler optimizes your program, it has to guess. Which functions are worth inlining? Which side of a branch is the common one? Which method does this interface call actually reach? At compile time it cannot know, so it uses heuristics. Profile-guided optimization (PGO) replaces the guessing with measurement: you run your program, record where it spends its time, and hand that recording back to the compiler for a second build.
PGO is a common feature of compiler systems. Google applied PGO to Chrome under Windows in 2016, reporting gains of up to 15%. I expect all mainstream Web browsers to be built with PGO.
There are now fancier techniques than mere heuristics with PGO. You can use AI to recognize patterns and so forth. But they are not always widely available.
Go has supported PGO since version 1.20. You collect a profile, and pass it to the compiler.
A CPU profile is a statistical record of where a program spends its time. While the program runs, the Go runtime interrupts it about a hundred times a second and writes down the call stack at that instant. After a few seconds you have thousands of such samples, and counting them tells you which functions were executing and who called them. In Go you produce one by wrapping the work you care about:
f, _ := os.Create("cpu.pprof")
pprof.StartCPUProfile(f) // from runtime/pprof
defer pprof.StopCPUProfile()
The compiler reads the call-stack counts and uses them for two things above all: inlining call sites that turn out to be hot, and devirtualizing interface calls whose target is nearly always the same concrete type.
I took three JSON documents that I wanted to parse:
twitter.json(632 kB), a nest of small objects with short string keyscanada.json(2.25 MB), essentially one enormous array of floating-point coordinatescitm_catalog.json(1.73 MB), deeply nested objects with numeric keys
I parse each of them with the standard library’s encoding/json into an interface{}. The baseline, with no profile, parses at 112 MB/s for twitter.json, 74 MB/s for canada.json and 116 MB/s for citm_catalog.json.
The procedure is three commands:
go build -o bench . # ordinary build
./bench -profile cpu.pprof -train twitter.json # collect a CPU profile
go build -pgo=cpu.pprof -o bench_pgo . # build again, with the profile
I did it three times, profiling each document on its own, and then measured all three documents against each of the three builds.
Each panel of the figure is one document being parsed, and the three bars inside it are the three PGO builds: the binary trained on twitter.json, the one trained on canada.json, and the one trained on citm_catalog.json. Bar height is the speed gain over the ordinary, profile-free build of that same document, in percent, so zero means PGO changed nothing and a bar below the axis means the PGO build was slower. The green bar in each panel is the matched case, where the profile was collected on the very document being measured.
The gains are modest. The best result is canada.json at +4.7%, and most differences are in the 2–3% range. Profiling one document usually helps the others, but not reliably. Profiling twitter.json gave a decent improvement everywhere: +3.1%, +2.0%, +2.8%. But profiling canada.json bought 4.7% on canada.json and essentially nothing anywhere else. Interestingly, profiling citm_catalog.json produced a mere +0.8% on its own document while helping twitter.json more.
A 3% speedup is not exciting in isolation, but it may come nearly for free. Observe how you may get slightly negative results for cases you did not train for. That’s expected generally, but the effect is modest in the case of Go because its optimizations are themselves modest in the first pace. That is, you are not getting a much an effect, but the process is less likely to backfire for other workloads.
How fast is C++26’s std::hive?
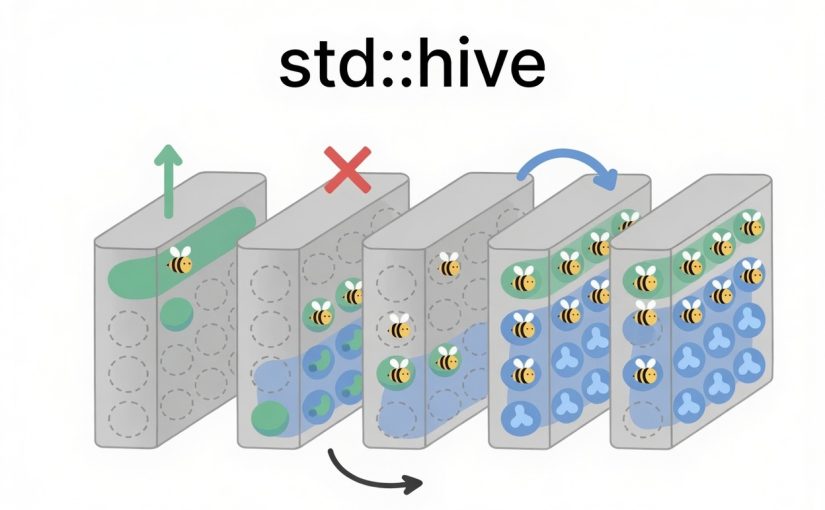
C++26 adds a new container to the standard library: std::hive. It is meant to occupy the ground between std::vector and std::list. Like a vector, it keeps its elements in contiguous blocks of memory, so scanning it does not require you to chase a pointer for every element. Like a list, it never moves an element once it has been inserted: your pointers, references and iterators stay valid, and you may erase any element in constant time without disturbing the others.
Internally, a hive is a linked list of blocks. Each block carries a skipfield: a small integer per slot that tells the iterator how many erased slots to jump over.
No standard library ships std::hive yet to my knowledge. Fortunately there is an implementation (plf::hive by Matt Bentley) as a single header file that you can use today.
I use elements of type uint64_t, GCC 16.1 with -O3 -march=native, on an Intel Xeon Gold 6548N (Emerald Rapids), pinned to one core. Numbers are nanoseconds per element, along with the cycles and instructions retired per element.
We start from an empty container and append a million values. The container is then destroyed.
A std::list needs one allocation per element, and glibc’s malloc and free together cost over 200 instructions per element. It is an order of magnitude behind everyone else. That is not news.
The interesting comparison is vector against hive. A hive is about twice the cost of a vector, and it needs twice the instructions. This is the price of the skipfield: every insertion writes an element and a skipfield entry, and maintains the block bookkeeping. Note that calling reserve on a hive does not help in my experiments.
Next we iterate over the the container and sum the values.
A hive iterates no faster than a linked list here, slightly slower, in fact, and about eight times slower than a vector. (Update: Joseph Garvin points out that I measure the happy case for the std::list in this instance where all the entries were allocated in sequence. The worst case scenario for std::list when the nodes are all over the heap can be much slower.)
The vector loop retires one instruction per element and finishes in 0.78 cycles: the processor is executing several elements at once. This is possible because the std::vector implementation benefits from autovectorization: the compiler recognizes that it can load several words at once in wide (SIMD). Further, it does not have to check the bitfield like the std::hive data structure.
We can check this. Walk the same container with two independent iterators, one starting halfway in, and count the cost per element visited:
The vector does not care: it was already throughput-bound. The hive and the list get nearly twice as fast per element, because two independent chains can be in flight at once. Hive iteration is latency-bound, exactly like list iteration. It merely has better locality.
That locality does show up when the data gets big. At ten million elements the list falls apart while the hive holds steady:
Erasing is what a hive is for, so it would be unfair not to look. I erase half the elements at scattered positions using std::remove_if:
The hive wins, but by less than you might expect, and at ten million elements the ordering reverses (1.3 ns for the vector against 2.5 for the hive). std::remove_if is a single streaming pass, and streaming passes are cheap. Of course the vector moved every surviving element and invalidated every pointer into it, which is precisely what a hive promises not to do.
Memory, measured by asking glibc how many bytes it has handed out, per live element:
A hive costs about a byte per element over a vector, for a payload of eight bytes, when the vector is packed tight. A list costs more due to the overhead of the linked list.
A vector built by push_back has a capacity that typically exceeds its size. Thus even if you have 8-byte entries, you will use, on average, more than 8 bytes per entry even for large vectors. You can recover the excess capacity with the shrink_to_fit method.
What should we conclude?
The std::hive data structure is not a faster vector. But it is a much better std::list. It gives you the same guarantees that make people reach for a list, stable references, cheap erasure anywhere, while using less memory.
Memory-level parallelism: AMD is the king
When your program asks for memory that is not in cache, the processor has to go to RAM. That trip costs on the order of 100 nanoseconds. On a 3 GHz core, that is about 300 cycles of doing nothing.
Memory latency has not improved in ten years. The 2016 Broadwell answers a random access in 100 ns. The 2025 Turin, with DDR5-6400 and every advantage of a decade of progress, takes 140 ns. It got worse.
The good news is that a modern core does not have to sit still. It can issue a second request before the first one comes back, and a third, and a tenth. The number of requests a single core can keep in flight is its memory-level parallelism. It is one of the most important numbers in software performance, and one of the least advertised: you will not find it on a spec sheet.
Thankfully, memory-level parallelism has improved a lot. To measure it, I use my testingmlp benchmark. The idea is a pointer chase. We build a 1 GiB array containing a single random cycle covering every element: each element holds the index of the next. Following the cycle is inherently serial. Each load has to complete before you know the address of the next one, so a single chase measures pure memory latency and nothing else. Then we run several such chases at once, from different starting points on the same cycle. We call these lanes. With two lanes, the core has two independent loads to work on. With twenty, twenty. We increase the number of lanes and watch the throughput. When adding a lane stops helping, we have found the limit. As my metric, I use the total estimated bandwidth.
I ran experiments on the Amazon cloud (AWS). The bandwidth shape is the same everywhere: a steep, nearly linear climb as we add lanes, then a knee, then a plateau.

How did it evolve over time? Intel went from 10 to 30, meaning that a single Intel core can sustain 30 memory requests at once in practice. AMD went from 15 to 58. Graviton went from 6 to 19.
Intel was flat for a long time. Broadwell and Cascade Lake both sit at 10 concurrent misses. Ice Lake doubled it to 20. Granite Rapids is at 30. Intel has roughly tripled in a decade, with all the gain arriving in the last two generations.
AMD started ahead and stayed ahead, then jumped. Naples was already at 15 in 2018, when Intel was at 10. Milan reached 22. And then Turin does something different in kind: 58 concurrent cache lines from a single core.
Graviton 1 was a toy: 6 concurrent misses. Graviton 2 doubled it, Graviton 3 went to 17, and then Graviton 4 essentially stood still at 18. Graviton 5 only reaches 19. But look at the latency panel: since 2017, Graviton 5 is the only chip in this entire collection that made a random access faster than its predecessor. AWS advertised better DRAM latency for Graviton 5, and that claim holds up.
So who wins? On bandwidth and memory-level parallelism, it is AMD, and it is not close. The Zen 5 core in the m8a instances sustains 58 concurrent cache-line fetches and 24.5 GiB/s of random-access throughput from one core. AMD is roughly twice as fast as Intel.
The raw output, the system information from each machine, and the scripts are in the usual place.
Note that Apple Silicon does even better, but it is another category.